Developers - Applications & Models#
Bringing the MONAI Model Zoo to AMD Instinct™ GPUs: Validated Inference on ROCm
Learn how to run validated inference for five MONAI Model Zoo bundles on AMD Instinct™ GPUs using a ROCm overlay.
Training EAGLE3 Speculative Decoding Draft Models on AMD Instinct MI350X with AMD Quark
Learn how the AMD Quark team trains EAGLE3.1 draft models from scratch on AMD Instinct MI350X GPUs using ROCm, vLLM, TorchSpec, and SPEED-Bench.
Accelerating MONAI Digital-Pathology Pipelines on AMD Instinct™ GPUs with hipCIM
In this blog you will measure a MONAI digital-pathology pipeline on AMD Instinct™ GPUs using hipCIM as the WSIReader backend.
Completing the GPU Performance Picture: Understanding TAF Alongside Peak FLOPs and MAF
Learn how Typical Attained FLOPs complements Peak FLOPs and Max-Achievable FLOPs, including the methodology and MI325X results
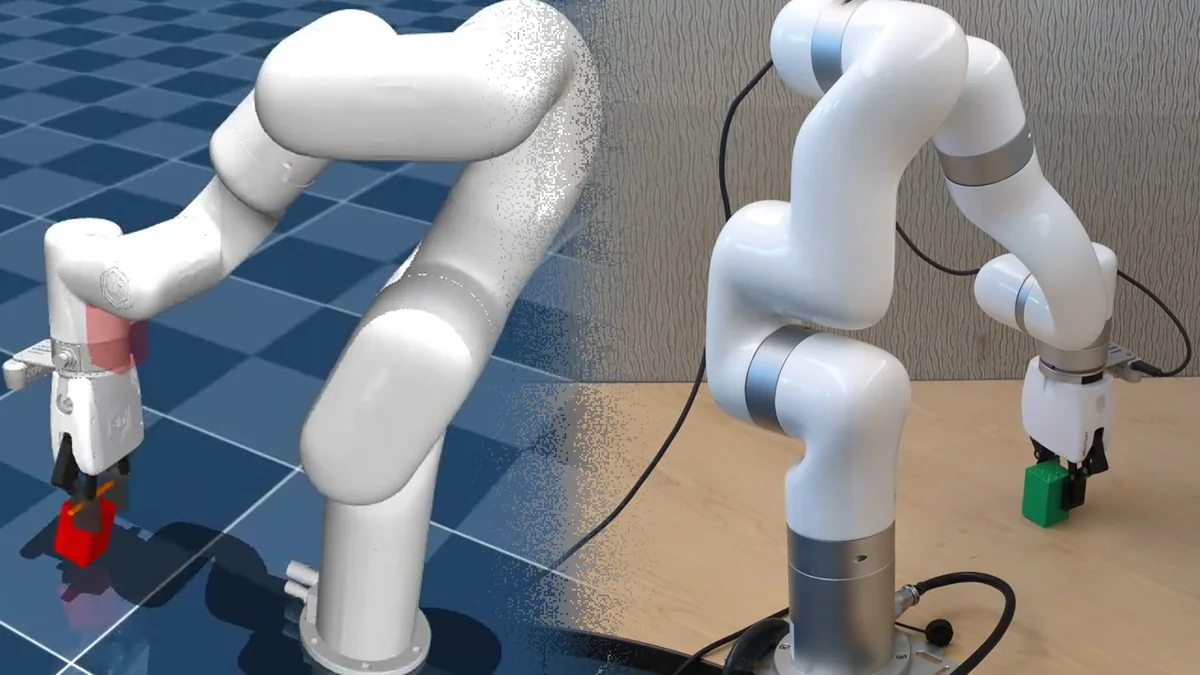
Unlocking Sim2Real for a Robotic Arm with RL Accelerated by AMD Instinct GPUs
Train an XArm-6 pick-and-lift policy with PPO in MuJoCo Warp on AMD Instinct GPUs, then transfer it to the real robot.
Reverse-Engineering hipBLASLt TensileLite Kernels: From Solution Name to a Tuning Config
Pin the pool's best kernel into a TensileLite tuning config by decoding its solution name, so an expanded re-tune can only match or beat it.
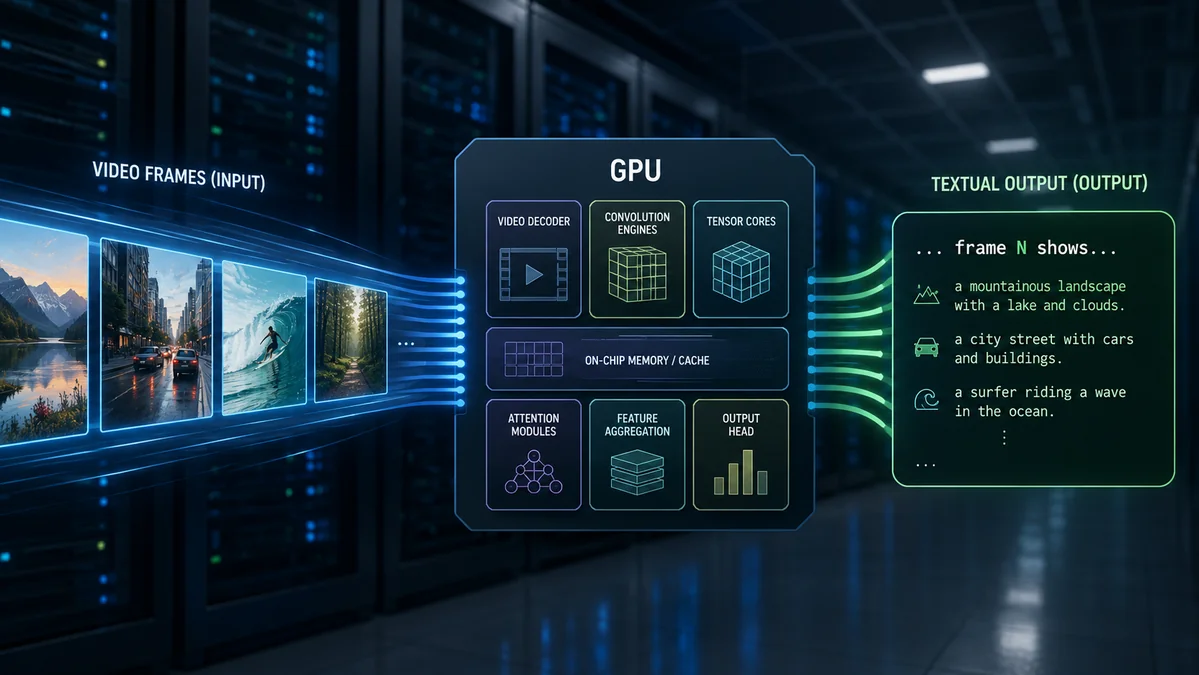
Building a High-Performance Video Inference Pipeline with ROCm Libraries Using C/C++
Learn how to build a powerful, GPU-accelerated video analytics pipeline with ROCm, combining rocDecode for fast hardware video decoding and MIGraphX for efficient AI-powered analysis and inference.
GEAK V3: Agent-Driven, Repository-Level GPU Kernel Optimization across HIP, Triton, and FlyDSL on AMD GPUs
Explore GEAK v3: agent-driven, repository-level GPU kernel optimization across HIP, Triton, and FlyDSL on AMD Instinct™ GPUs.
Triton-Based Optimization of Video Sparse Attention on ROCm
Optimize video sparse attention on ROCm with GEAK and linear global context for faster, more stable video generation on AMD GPUs.
Towards Feature Complete Triton Support in JAX-Triton
Learn what new features were added to JAX-Triton and how that could help you write or reuse more efficient and readable GPU kernels in JAX.
Building a GPU-Resident YOLO26 Object Detection Pipeline on the AMD Radeon™ AI PRO R9700 GPU
Build a GPU-resident object detection pipeline on AMD GPUs with rocDecode, DLPack, and MIGraphX. Frames stay in VRAM end to end.
MXFP6 and MXFP4 Mixed Precision for Accelerating Dense LLMs on AMD Instinct MI355X
W_MXFP4_A_MXFP6 quantization on AMD Instinct MI355X improves LLM throughput and latency while recovering accuracy versus MXFP4.