HPC Blogs#
Completing the GPU Performance Picture: Understanding TAF Alongside Peak FLOPs and MAF
Learn how Typical Attained FLOPs complements Peak FLOPs and Max-Achievable FLOPs, including the methodology and MI325X results
ROCm 10.1: Breaking the Data-Movement Bottleneck
ROCm 10.1 targets the data-movement bottleneck with AMD Infinity Storage, NUMA-aware memory, and a modernized stack.
Performance Profiling on AMD GPUs - Part 6: Advanced Thread Trace (ATT) - The Microscope for Your Application
Explore rocprofv3 ATT and ROCprof Compute Viewer to trace GPU kernels and explain stalls, waits, and memory-bound performance.
Benchmarking Kimi-K3 Across vLLM, SGLang, and ATOM on MI350X
Learn how one declarative madengine command benchmarks day-0 Kimi-K3 across vLLM, SGLang, and ATOM on AMD Instinct MI350X.
Fast Image Generation and Editing with SGLang Diffusion on AMD GPUs
Serve and benchmark diffusion models for image generation and editing on AMD Instinct GPUs using SGLang Diffusion on ROCm.
Towards Feature Complete Triton Support in JAX-Triton
Learn what new features were added to JAX-Triton and how that could help you write or reuse more efficient and readable GPU kernels in JAX.
Running Variational Quantum Eigensolver with Qiskit Aer on AMD Instinct
A step-by-step guide to running GPU-accelerated VQE for quantum chemistry with Qiskit Aer on AMD Instinct using ROCm.
Programming Tensor Descriptors in Composable Kernel (CK)
Learn how to use TensorDescriptor in Composable Kernel (CK) to manage multi-dimensional data layouts and write efficient GPU kernels on AMD GPUs.
A Deep Dive into LDS Optimizations on AMD Instinct MI450 GPUs
Learn how to optimize LDS traffic in Gluon kernels on AMD Instinct MI450 GPUs using transposed loads and partition-conflict-free layouts.
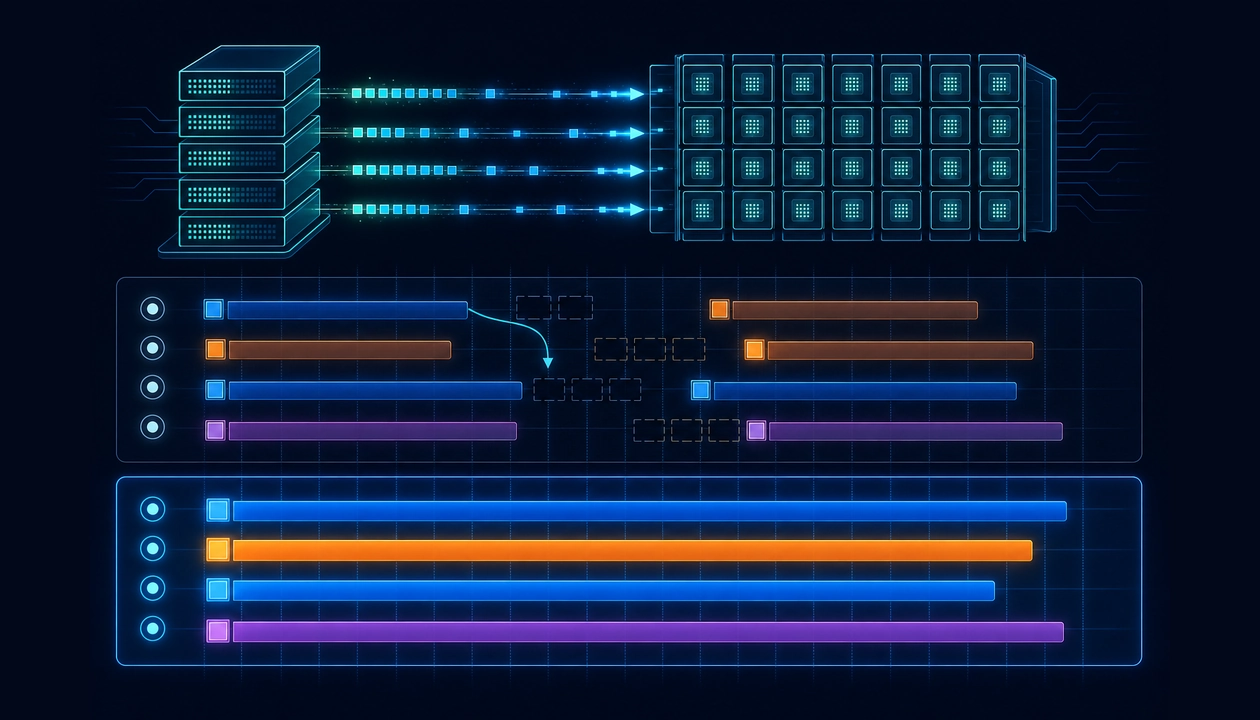
Memory Instruction Scheduling for Lock-Stepped Kernels on AMD Instinct™ MI300X: Introducing the Series
Explore how instruction scheduling eases stalls on AMD Instinct MI300X in a new blog series. This intro covers the motivating example and methodology.
Using ODC to Accelerate AMD SFT Training
Learn how we ported ODC on-demand P2P communication to AMD Instinct MI300X to cut FSDP bubbles and speed up variable-length SFT training.
AMD GPU Operator v1.5.0: DRA Support, Automated GPU Node Recovery, and Expanded Kubernetes Infrastructure Control
Discover how AMD GPU Operator v1.5.0 improves GPU scheduling, automates node recovery, and expands Kubernetes control.
Styled Text Image Generation with Eruku on AMD
Hands-on, reproducible guide to train and run Eruku on LUMI supercomputer, powered by AMD Instinct MI250X GPUs.
Continuing the Momentum: Refining ROCm For The Next Wave Of AI and HPC
ROCm 7.1 builds on 7.0’s AI and HPC advances with faster performance, stronger reliability, and streamlined tools for developers and system builders.
ROCm 7.0: An AI-Ready Powerhouse for Performance, Efficiency, and Productivity
Discover how ROCm 7.0 integrates AI across every layer, combining hardware enablement, frameworks, model support, and a suite of optimized tools
Unlocking GPU-Accelerated Containers with the AMD Container Toolkit
Simplify GPU acceleration in containers with the AMD Container Toolkit—streamlined setup, runtime hooks, and full ROCm integration.
Stay informed
- Subscribe to our RSS feed (Requires an RSS reader available as browser plugins.)
- Signup for the ROCm newsletter
- View our blog statistics