Developers Blogs#
Completing the GPU Performance Picture: Understanding TAF Alongside Peak FLOPs and MAF
Learn how Typical Attained FLOPs complements Peak FLOPs and Max-Achievable FLOPs, including the methodology and MI325X results
ROCm 10.1: Breaking the Data-Movement Bottleneck
ROCm 10.1 targets the data-movement bottleneck with AMD Infinity Storage, NUMA-aware memory, and a modernized stack.
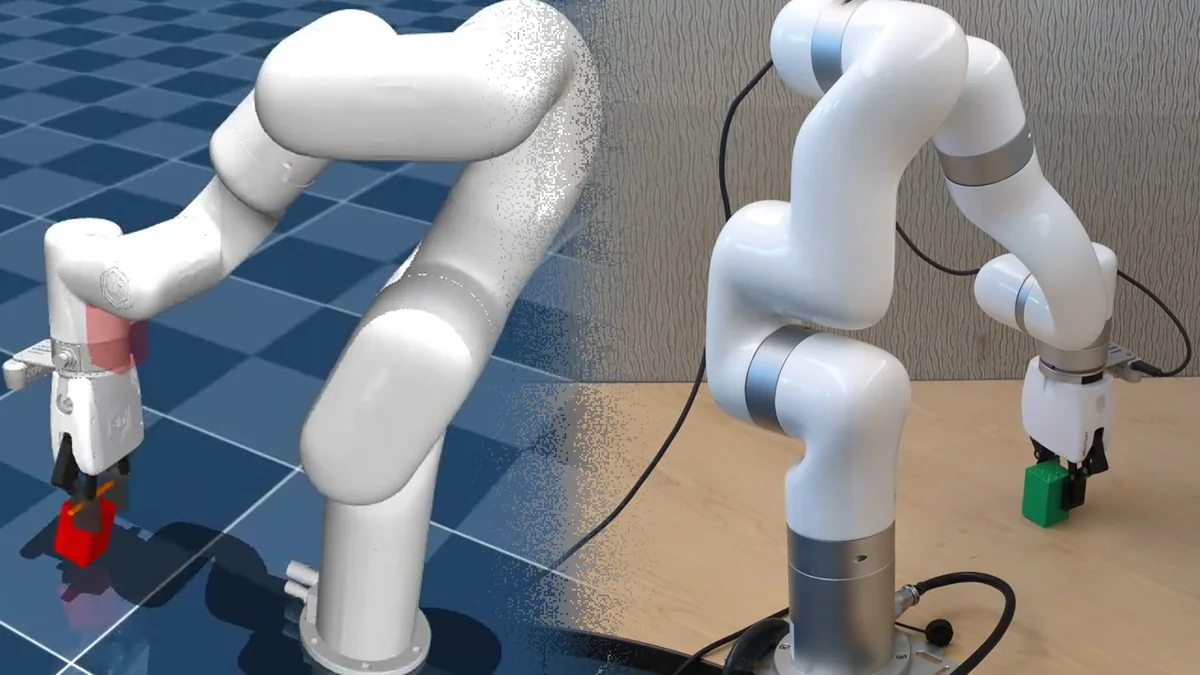
Unlocking Sim2Real for a Robotic Arm with RL Accelerated by AMD Instinct GPUs
Train an XArm-6 pick-and-lift policy with PPO in MuJoCo Warp on AMD Instinct GPUs, then transfer it to the real robot.
Debugging Logprob Mismatches in LLM Reinforcement Learning
Learn to debug logprob mismatches between rollout and training with Qwen3 examples on AMD Instinct MI355X GPUs.
Reverse-Engineering hipBLASLt TensileLite Kernels: From Solution Name to a Tuning Config
Pin the pool's best kernel into a TensileLite tuning config by decoding its solution name, so an expanded re-tune can only match or beat it.
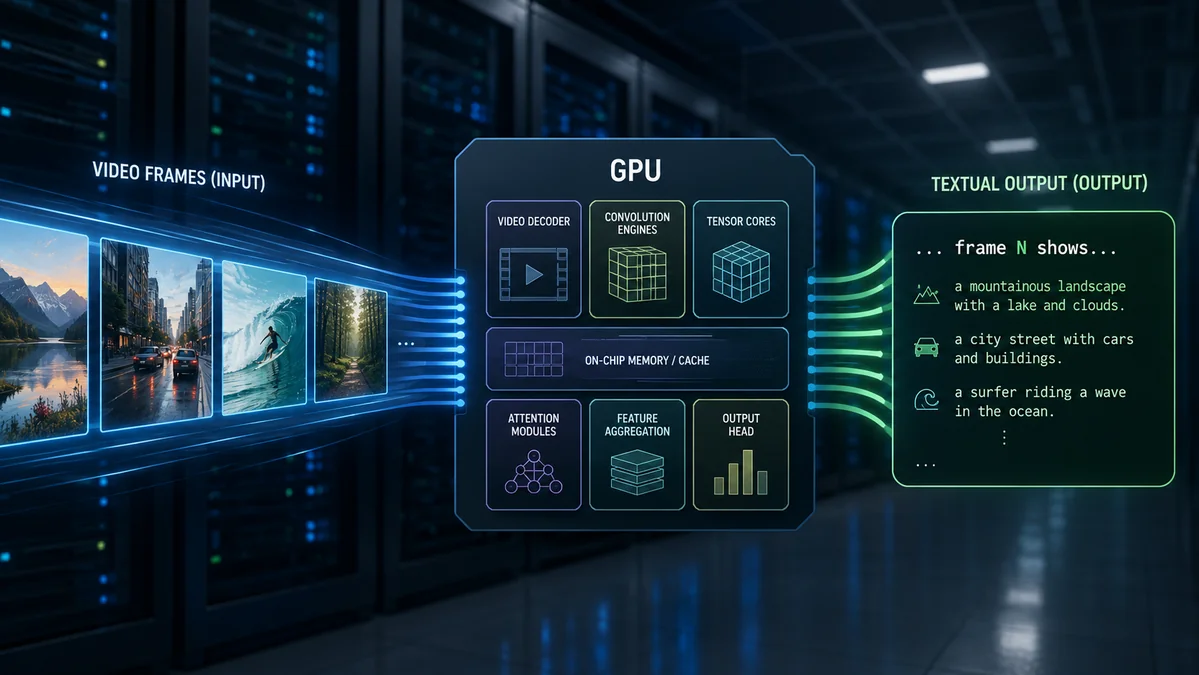
Building a High-Performance Video Inference Pipeline with ROCm Libraries Using C/C++
Learn how to build a powerful, GPU-accelerated video analytics pipeline with ROCm, combining rocDecode for fast hardware video decoding and MIGraphX for efficient AI-powered analysis and inference.
GEAK V3: Agent-Driven, Repository-Level GPU Kernel Optimization across HIP, Triton, and FlyDSL on AMD GPUs
Explore GEAK v3: agent-driven, repository-level GPU kernel optimization across HIP, Triton, and FlyDSL on AMD Instinct™ GPUs.
Triton-Based Optimization of Video Sparse Attention on ROCm
Optimize video sparse attention on ROCm with GEAK and linear global context for faster, more stable video generation on AMD GPUs.
Performance Profiling on AMD GPUs - Part 6: Advanced Thread Trace (ATT) - The Microscope for Your Application
Explore rocprofv3 ATT and ROCprof Compute Viewer to trace GPU kernels and explain stalls, waits, and memory-bound performance.
Hyperloom: A Multi-Agent Harness for Autonomous Inference Optimization on AMD GPUs
Hyperloom is a multi-agent harness that autonomously optimizes LLM inference on AMD Instinct GPUs, reaching a median 1.73x throughput gain.
Thread Trace Part 1: ROCprof Compute Viewer
Learn to capture thread traces with rocprofv3 and analyze instruction timing, stalls, utilization, and counters in ROCprof Compute Viewer.
Iteratively Tuning hipBLASLt TensileLite Kernels: A Smaller Search, a Faster Kernel
Learn why a small iterative search beats a big one-shot sweep for hipBLASLt TensileLite kernels, in less time and with no risk of regression.
ROCm 10.0: A Decade of Open Compute, Built for the Age of Agentic AI
Explore what's new in ROCm 10.0, headlined by ROCm.AI, the ROCm CLI, AMD Skills, and Hyperloom, alongside the ROCm Core SDK and platform-wide improvements
AUP Learning Cloud: Streamlining AI Education on AMD
An all-in-one ROCm JupyterHub platform that deploys GPU-ready AI teaching environments on AMD hardware with one installer and open-source teaching labs.

Introducing AMD CDNA™ 5 and the AMD Helios™ Rackscale Solution
Introducing AMD CDNA 5, the AMD Instinct MI455X GPU, and the AMD Helios rackscale solution: an open, integrated platform for rack-scale AI.
ROCm 7.14: TheRock Goes Production and Expands AMD's AI Software Platform
Explore what's new in ROCm 7.14: TheRock goes production, expanded hardware support, stronger AI frameworks, and enhanced profiling tools.
Stay informed
- Subscribe to our RSS feed (Requires an RSS reader available as browser plugins.)
- Signup for the ROCm newsletter
- View our blog statistics