AI Blogs#
Automating Performance Bottleneck Identification with the TraceLens Agent
TraceLens Agent is an agentic workflow that examines GPU traces to deliver a prioritized optimization report, detailing root causes and fixes.
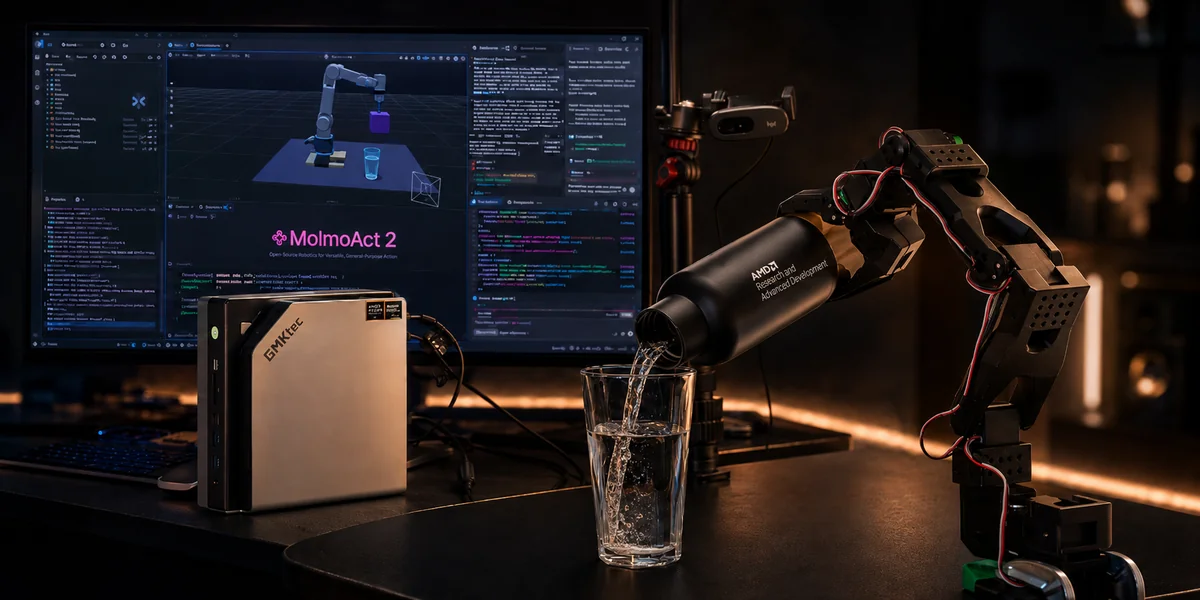
Running MolmoAct2 Robot Policy on an AMD Ryzen AI Max+ 395 Mini PC
In this tutorial, users are introduced to a state of the art vision-language-action model and the steps to implement the model directly optimized for the AMD Ryzen AI Max+ 395 Computer.
AIM: Unified User Experience from Profile Discovery to Deployment
Learn how AIMs offer a unified user experience as you explore and deploy them across AMD Instinct, Radeon PRO, and EPYC.
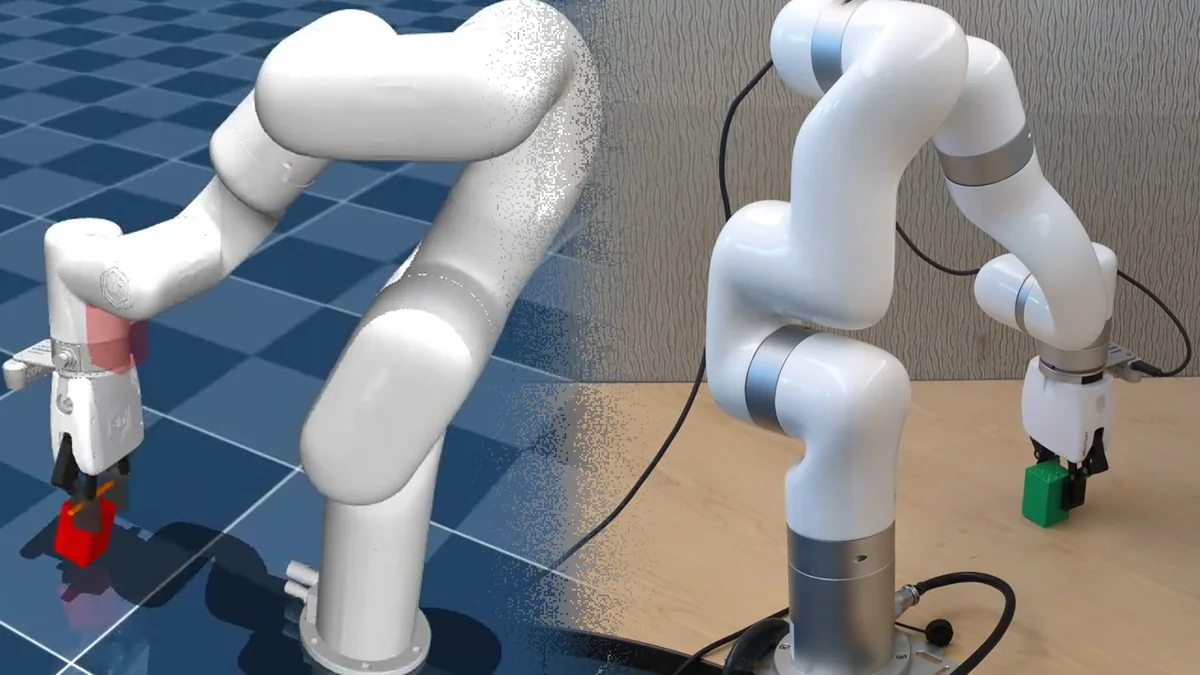
Unlocking Sim2Real for a Robotic Arm with RL Accelerated by AMD Instinct GPUs
Train an XArm-6 pick-and-lift policy with PPO in MuJoCo Warp on AMD Instinct GPUs, then transfer it to the real robot.
Verl 0.9.0 on ROCm™ 10.0: Next-Generation RL Post-Training on AMD Instinct™ GPUs
Enable Verl 0.9.0 on ROCm™ 10. Native AMD platform support, vLLM 0.27 and SGLang in one image, and updated async GRPO/DAPO recipes on AMD Instinct™ GPUs.
Model Weight Profiles: Where Do the Parameters Go?
Introduce Model Weight Profiles and compare embeddings, attention, and dense layers so checkpoint size and quantization savings make sense.
Local Quantization and Multi-Backend Deployment with AMD Quark on Strix Halo
Quantize a 35B MoE model directly on AMD Strix Halo with AMD Quark, export to GGUF and safetensors, validate with llama.cpp and vLLM, and deploy through Lemonade.
Zebra-HyLo: Upcycling Transformers into Long-Context Hybrid LLMs on AMD Instinct™ GPUs
Upcycle pretrained Transformers into long-context hybrid MLA + linear models on AMD Instinct MI300X GPUs, with 14 open checkpoints and training code.
UltraQuant on AMD Instinct: More Efficient Agentic Serving for Qwen3.8-MXFP4
A native 4-bit MXFP4 KV cache that speeds up Qwen3.8 decode over 8-bit KV on AMD Instinct MI355X, with no accuracy loss.
Debugging Logprob Mismatches in LLM Reinforcement Learning
Learn to debug logprob mismatches between rollout and training with Qwen3 examples on AMD Instinct MI355X GPUs.
Hyperloom: A Multi-Agent Harness for Autonomous Inference Optimization on AMD GPUs
Hyperloom is a multi-agent harness that autonomously optimizes LLM inference on AMD Instinct GPUs, reaching a median 1.73x throughput gain.
Implementing a High-Performance Custom Diffusion Attention Kernel with FlyDSL
Learn how to implement and optimize flexible, high-performance diffusion attention kernels with FlyDSL.
AUP Learning Cloud: Streamlining AI Education on AMD
An all-in-one ROCm JupyterHub platform that deploys GPU-ready AI teaching environments on AMD hardware with one installer and open-source teaching labs.

Introducing AMD CDNA™ 5 and the AMD Helios™ Rackscale Solution
Introducing AMD CDNA 5, the AMD Instinct MI455X GPU, and the AMD Helios rackscale solution: an open, integrated platform for rack-scale AI.
Styled Text Image Generation with Eruku on AMD
Hands-on, reproducible guide to train and run Eruku on LUMI supercomputer, powered by AMD Instinct MI250X GPUs.
Elevate Your LLM Inference: Autoscaling with Ray, ROCm 7.0.0, and SkyPilot
Learn how to use multi-node and multi-cluster autoscaling in the Ray framework on ROCm 7.0.0 with SkyPilot
Stay informed
- Subscribe to our RSS feed (Requires an RSS reader available as browser plugins.)
- Signup for the ROCm newsletter
- View our blog statistics