Developers - Software Tools & Optimizations#
GLM-5.2 AgentX on AMD Instinct MI355X: Boosting Throughput and Interactivity
Learn how cache and kernel optimizations raised GLM-5.2 AgentX throughput and interactivity on AMD Instinct MI355X.
FlyDSL Mono Kernels for High-Interactivity LLM Serving in ATOM
FlyDSL mono kernels cut decode latency in ATOM, with MiniMax-M3 and DeepSeek-V4.1 results.
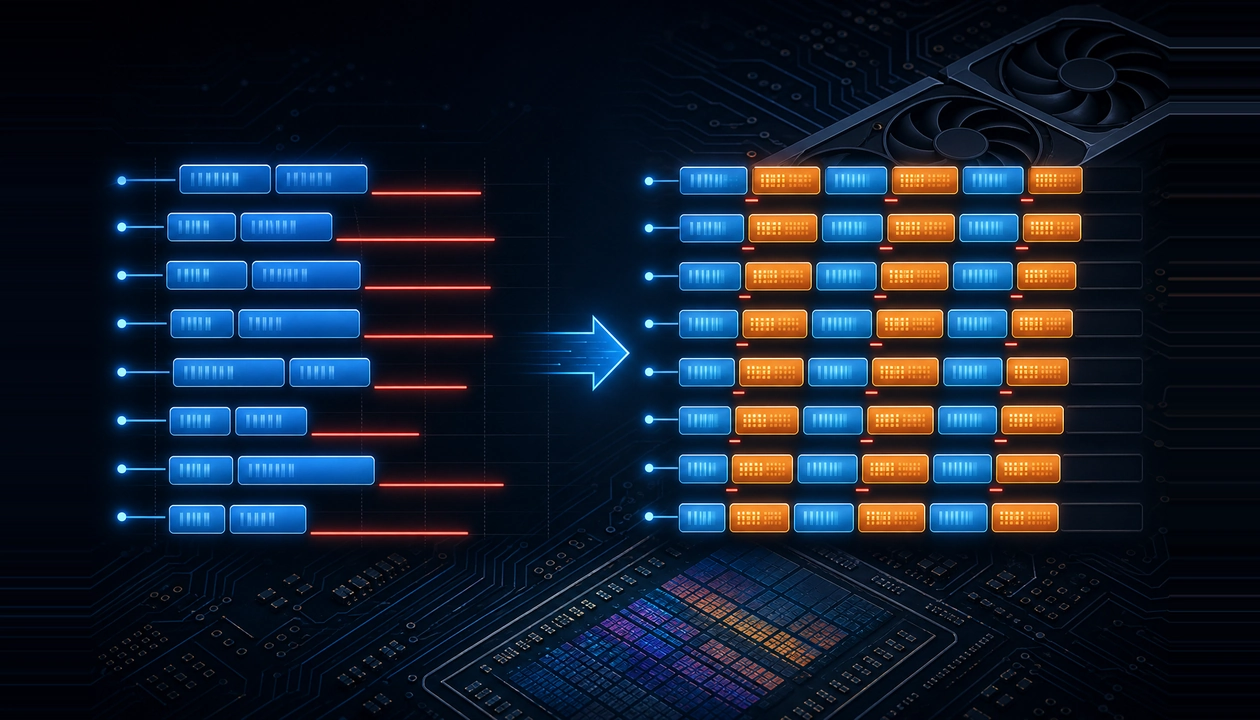
Device Memory Load Issue Stalls and Scheduling Opportunities in Lock-Stepped Kernels on AMD Instinct™ MI300X
Diagnosing and reducing device-memory load issue stalls in lock-stepped kernels on AMD Instinct MI300X by interleaving compute.
Faster Stable Diffusion on AMD Ryzen™ AI with TeaCache
In this blog, you will learn how to speed up Stable Diffusion 3 and 3.5 on AMD Ryzen AI NPUs with TeaCache, without retraining.
Two Waves, One Stage Apart: Warp-Pipelining Triton GEMMs on AMD Instinct
Use warp-pipelining to overlap matrix work and data preparation in compute-bound Triton GEMMs on AMD Instinct GPUs.
Group-GEMM in XLA: Making Mixture-of-Experts Fast and Memory-Efficient
Learn how to make JAX/MaxText MoE training more efficient with two new OpenXLA Group-GEMM backends for ragged-dot: ROCm hipBLASLt and generic Triton.
FP8 GEMM Optimization on AMD RDNA™ 4 Architecture
Learn how to port an FP16 GEMM kernel to FP8 on AMD RDNA 4 and use the smaller element size to unlock larger tiles and deeper K slices.
Scaling 3D Gaussian Splatting with Distributed Compute: Why One GPU Is Never Enough
Learn how to scale 3D Gaussian splatting across GPUs with distributed training, RCCL, and real-world optimization tips for AMD Instinct GPUs
MoE Training Optimization with Primus
Learn how to speed up MoE training on AMD Instinct GPUs with Primus: a fused MoE megakernel, FP8/MXFP8 expert GEMMs, and training-at-scale tuning.
hipCIM 26.06: GPU-Accelerated Whole-Slide Image I/O on AMD Instinct™ GPUs
In this blog you will see how hipCIM 26.06 reads whole-slide images on AMD Instinct™ GPUs, and how fast and faithfully it decodes them.
FP16 GEMM Optimization on AMD RDNA™ 3 and RDNA™ 4 Architectures
Learn how to build an FP16 GEMM kernel with WMMA on AMD RDNA 3 and RDNA 4, one optimization at a time, and approach hipBLASLt performance.
Debugging Logprob Mismatches in LLM Reinforcement Learning
Learn to debug logprob mismatches between rollout and training with Qwen3 examples on AMD Instinct MI355X GPUs.