Software tools & optimizations - Page 6#
Discover the latest blogs about ROCm software tools, libraries, and performance optimizations to help you get the most out of your AMD hardware.
Building and Deploying Custom hipBLASLt Libraries on AMD Instinct GPUs
Learn how to manage hipBLASLt environments with custom source builds, RPM/DEB packaging, and version switching on AMD Instinct GPUs.
ATOMesh: Unlocking AMD Hardware for Scalable LLM Serving
Learn how ATOMesh unlocks scalable LLM serving on AMD Instinct GPUs through distributed inference orchestration and ROCm-native execution.
ATOM: Unlocking Extreme AMD Instinct Inference with Software-Hardware Co-Optimization
A technical walkthrough of ATOM on AMD Instinct GPUs, covering architecture, feature scope, model coverage, and practical benchmark dashboard usage.
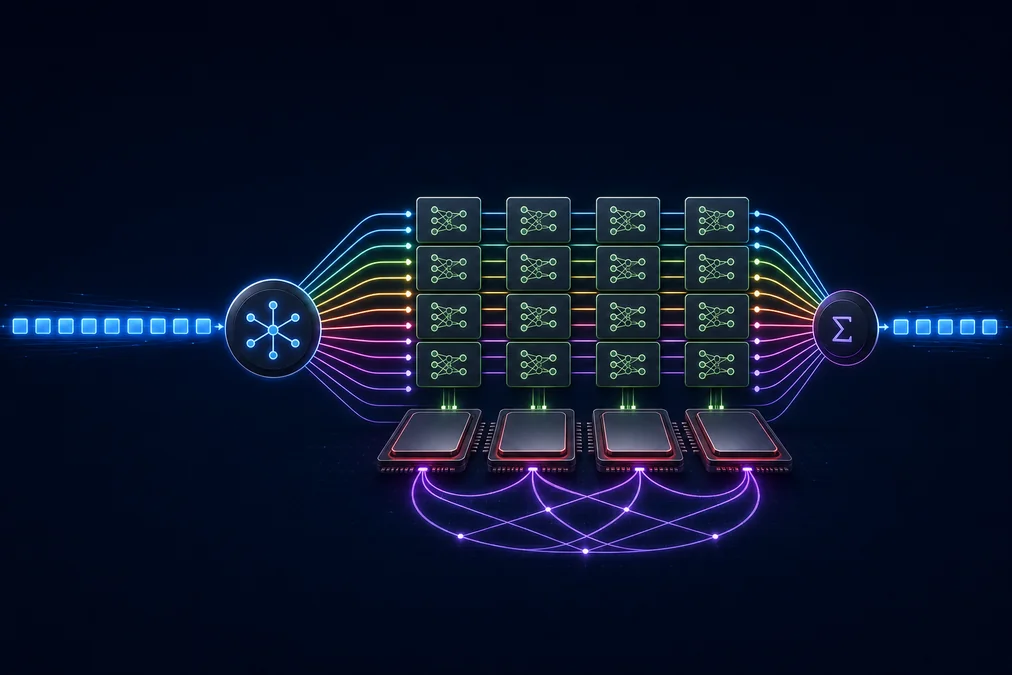
Dropless MoE Training in JAX with Primus-Turbo
Learn how to train dropless MoE in JAX/MaxText with Primus-Turbo's grouped GEMM and DeepEP all-to-all for faster, more memory-efficient training.
Adapting AIM LLMs For Specific Use Cases Through Fine-Tuning in AMD AI Workbench
Learn how to adapt and fine-tune an AIM LLM in AMD AI Workbench GUI for specialization or specific use cases.
Performance Profiling on AMD GPUs - Part 4: Fortran OpenMP Offload Edition
Guides developers through profiling and optimizing Fortran OpenMP GPU offload applications using ROCm tools
Deep Dive Into 4-Wave Interleave FP8 GEMM
Learn how to build faster FP8 GEMM kernels on AMD CDNA™4 using 4-wave interleaving to hide memory latency and maximize Matrix Core utilization.
From Build to Benchmark: ONNX Model Serving with Triton Inference Server on AMD GPUs
Step-by-step guide to building, deploying, and benchmarking ONNX models with Triton Inference Server and MIGraphX on AMD GPUs
From Naive to Near-Peak: Building High-Performance GEMM Kernels with Gluon
Learn how a Gluon GEMM tutorial teaches profiling-driven AMD GPU optimization from FP16 baseline to BF8 and MXFP4 kernels.
vLLM-ATOM: Unlocking Native AMD Performance in the vLLM Ecosystem
Use ATOM as an out-of-tree vLLM plugin to keep vLLM compatibility while enabling AMD-optimized attention, model execution, and multi-model support including Kimi-K2.5.
TraceLens: Democratizing AI Performance Analysis
Explore how TraceLens automates profiler trace analysis to pinpoint bottlenecks and optimize AI workloads.
Primus Projection: Estimate Memory and Performance Before You Train
Learn how to use the Primus projection tool to estimate memory and performance for large-scale LLM training on AMD Instinct™ accelerator platforms.