Applications & models - Page 3#
Explore the latest blogs about applications and models in the ROCm ecosystem, including machine learning frameworks, AI models, and application case studies.
AIM: Unified User Experience from Profile Discovery to Deployment
Learn how AIMs offer a unified user experience as you explore and deploy them across AMD Instinct, Radeon PRO, and EPYC.
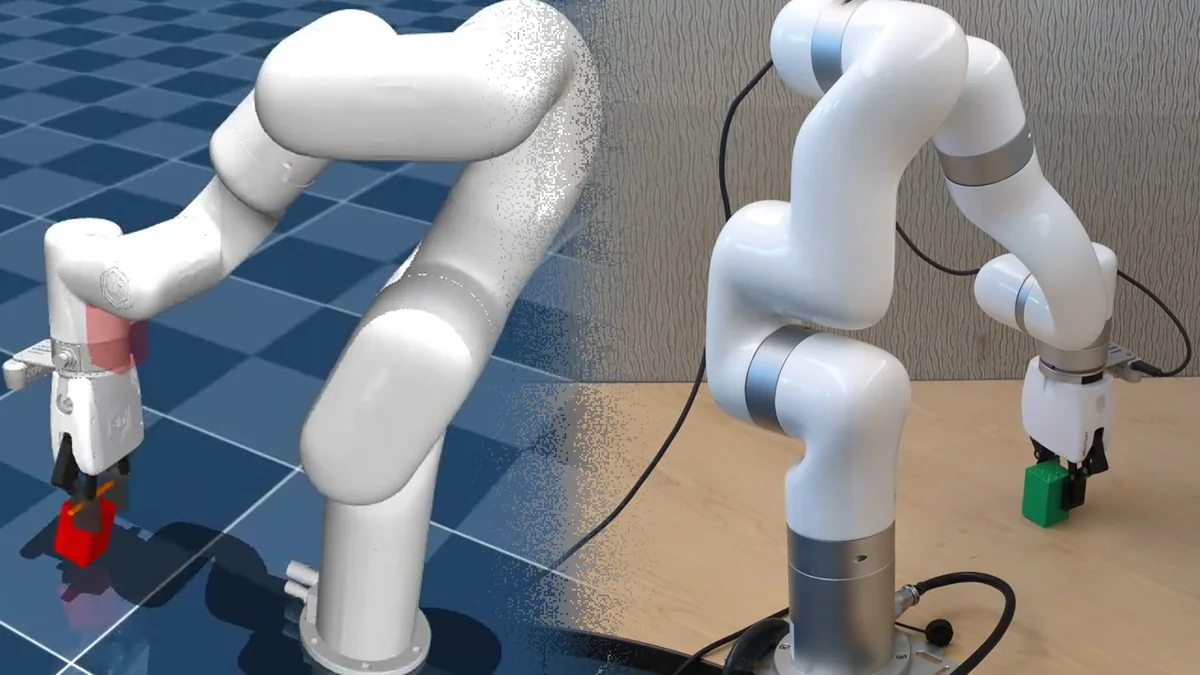
Unlocking Sim2Real for a Robotic Arm with RL Accelerated by AMD Instinct GPUs
Train an XArm-6 pick-and-lift policy with PPO in MuJoCo Warp on AMD Instinct GPUs, then transfer it to the real robot.
Verl 0.9.0 on ROCm™ 10.0: Next-Generation RL Post-Training on AMD Instinct™ GPUs
Enable Verl 0.9.0 on ROCm™ 10. Native AMD platform support, vLLM 0.27 and SGLang in one image, and updated async GRPO/DAPO recipes on AMD Instinct™ GPUs.
Model Weight Profiles: Where Do the Parameters Go?
Introduce Model Weight Profiles and compare embeddings, attention, and dense layers so checkpoint size and quantization savings make sense.
Local Quantization and Multi-Backend Deployment with AMD Quark on Strix Halo
Quantize a 35B MoE model directly on AMD Strix Halo with AMD Quark, export to GGUF and safetensors, validate with llama.cpp and vLLM, and deploy through Lemonade.
Zebra-HyLo: Upcycling Transformers into Long-Context Hybrid LLMs on AMD Instinct™ GPUs
Upcycle pretrained Transformers into long-context hybrid MLA + linear models on AMD Instinct MI300X GPUs, with 14 open checkpoints and training code.
Benchmarking Kimi-K3 Across vLLM, SGLang, and ATOM on MI350X
Learn how one declarative madengine command benchmarks day-0 Kimi-K3 across vLLM, SGLang, and ATOM on AMD Instinct MI350X.
Serving GLM-5.2-MXFP4 on AMD Instinct™ MI355X: When Prefill Context Parallelism Pays
Learn when prefill context parallelism pays on AMD Instinct MI355X: 43-54% more throughput on long prompts with GLM-5.2-MXFP4, and when it loses.
Reproducing AMD MLPerf Inference v6.1 Submission Results
In this blog, we share the technical details of how we accomplish the results in our MLPerf Inference v6.1 submission.
Technical Dive into AMD MLPerf Inference v6.1 Submission
Learn about the ROCm optimizations powering dlrm-v3, llama2-70b, and gpt-oss-120b performance.
DFlash Speculative Decoding on AMD Instinct MI355X: Up to 5× Faster Qwen3.5 Inference
Explore how DFlash speculative decoding delivers up to 5× faster Qwen3.5 inference on AMD Instinct MI355X with vLLM on ROCm.
Knowledge Graph Integration With Poro2 For Enriching Medical Text Processing
Learn how to integrate a medical knowledge graph with Poro2 LLM via MCP to simplify medical text on AMD Instinct MI300X GPUs