Applications & models - Page 2#
Explore the latest blogs about applications and models in the ROCm ecosystem, including machine learning frameworks, AI models, and application case studies.
Onboard and Deploy Custom Models in AMD AI Workbench
Learn how to deploy custom models in AMD AI Workbench, utilizing the AIM Engine, orchestration, scaling, profile parameters and API keys.
Efficient MiniMax-M3 Inference on AMD Instinct GPUs with ATOM and ATOMesh
Serve and benchmark MiniMax-M3 on AMD Instinct MI355X GPUs using ATOM and ATOMesh with EAGLE3 speculative decoding.
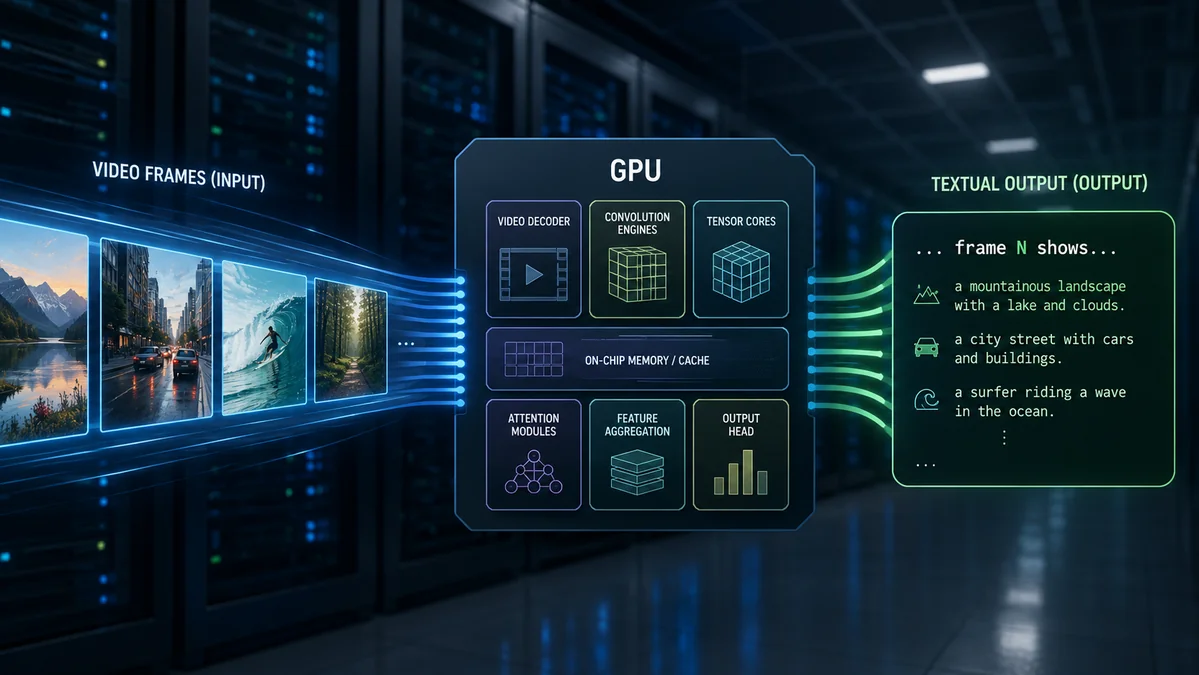
Building a High-Performance Video Inference Pipeline with ROCm Libraries Using C/C++
Learn how to build a powerful, GPU-accelerated video analytics pipeline with ROCm, combining rocDecode for fast hardware video decoding and MIGraphX for efficient AI-powered analysis and inference.
GEAK V3: Agent-Driven, Repository-Level GPU Kernel Optimization across HIP, Triton, and FlyDSL on AMD GPUs
Explore GEAK v3: agent-driven, repository-level GPU kernel optimization across HIP, Triton, and FlyDSL on AMD Instinct™ GPUs.
Multi-Accelerator Support for AIMs and AMD Solution Blueprints
Deploy and run AIMs and AMD Solution Blueprints across AMD Instinct™ GPUs, AMD EPYC™ CPUs, and AMD Radeon™ GPUs
Local Image and Video Generation on AMD Ryzen™ AI Max+ Processor (Windows)
Run ComfyUI natively on Windows on AMD Ryzen AI Max+ with ROCm 7.2.1—SDXL, Flux, and video workflows on the Radeon 8060S, no WSL.
QuickReduce INT3 Quantization and Benchmarking on MI355
Learn how QuickReduce uses INT3 quantization to accelerate all-reduce communication and evaluate its performance and accuracy on AMD Instinct MI355 GPUs.
Triton-Based Optimization of Video Sparse Attention on ROCm
Optimize video sparse attention on ROCm with GEAK and linear global context for faster, more stable video generation on AMD GPUs.
Fast Image Generation and Editing with SGLang Diffusion on AMD GPUs
Serve and benchmark diffusion models for image generation and editing on AMD Instinct GPUs using SGLang Diffusion on ROCm.
AMD Instinct™ Network Traffic, Congestion Trends, and Harmonics in Scale-Out Networks for AI Training Clusters
Explore how synchronized GPU collectives create harmonic congestion in AI clusters and the strategies to diagnose and mitigate it.
Towards Feature Complete Triton Support in JAX-Triton
Learn what new features were added to JAX-Triton and how that could help you write or reuse more efficient and readable GPU kernels in JAX.
Efficient Hyperparameter Optimization for Autonomous Driving Models with AMD Instinct GPU Partitioning
Accelerate HPO for autonomous driving models using AMD MI300X GPU partitioning for higher throughput, efficiency, and parallelism.