HPC Blogs#
GPU-Initiated DMA Copy Engines in RCCL and rocSHMEM
Learn how GPU-initiated SDMA engines in RCCL and rocSHMEM offload data transfers to free compute units and maximize scale-up bandwidth.
Introducing the ROCm Handbooks
Discover the ROCm handbooks: book-style HTML and PDF guides that take you from your first HIP kernel to optimizing code for AMD GPUs.
Performance Profiling on AMD GPUs - Part 7: AI/PyTorch® Edition
Profile and optimize a PyTorch Evoformer (TinyOpenFold) training workload on AMD Instinct GPUs using rocprofv3, rocprof-compute, and rocprof-sys.
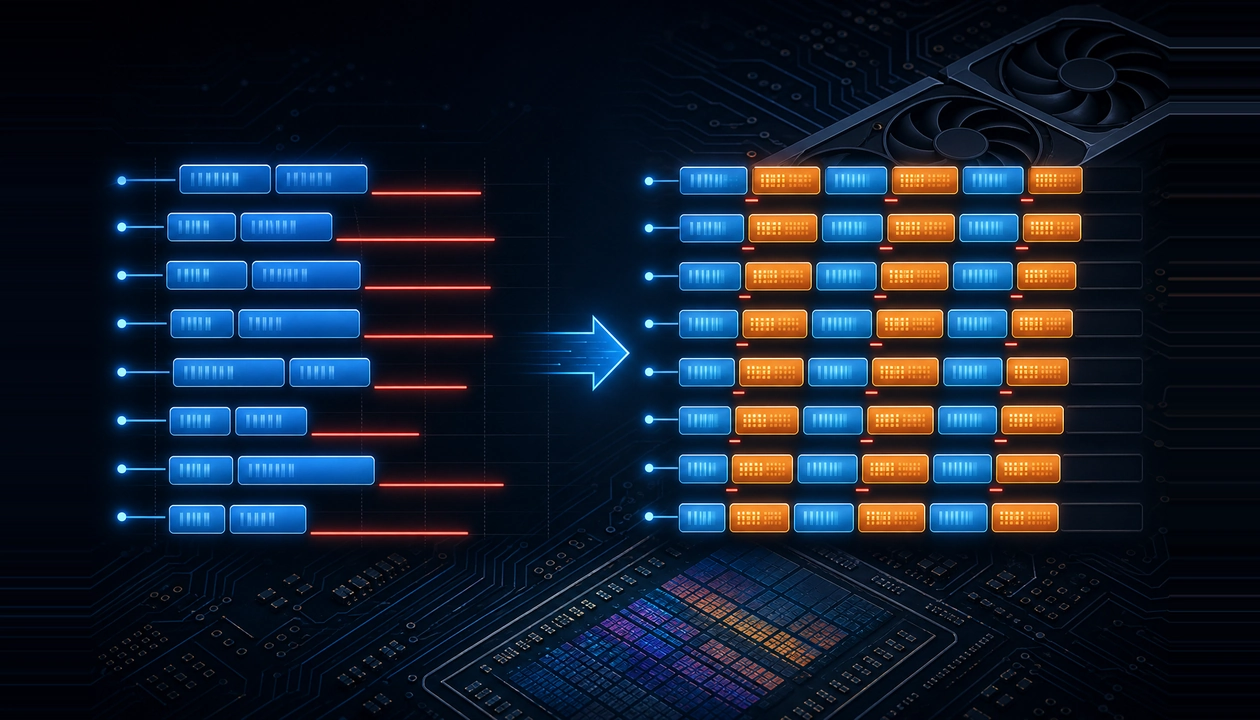
Device Memory Load Issue Stalls and Scheduling Opportunities in Lock-Stepped Kernels on AMD Instinct™ MI300X
Diagnosing and reducing device-memory load issue stalls in lock-stepped kernels on AMD Instinct MI300X by interleaving compute.
Completing the GPU Performance Picture: Understanding TAF Alongside Peak FLOPs and MAF
Learn how Typical Attained FLOPs complements Peak FLOPs and Max-Achievable FLOPs, including the methodology and MI325X results
ROCm 10.1: Breaking the Data-Movement Bottleneck
ROCm 10.1 targets the data-movement bottleneck with AMD Infinity Storage, NUMA-aware memory, and a modernized stack.
Performance Profiling on AMD GPUs - Part 6: Advanced Thread Trace (ATT) - The Microscope for Your Application
Explore rocprofv3 ATT and ROCprof Compute Viewer to trace GPU kernels and explain stalls, waits, and memory-bound performance.
Benchmarking Kimi-K3 Across vLLM, SGLang, and ATOM on MI350X
Learn how one declarative madengine command benchmarks day-0 Kimi-K3 across vLLM, SGLang, and ATOM on AMD Instinct MI350X.
A Deep Dive into LDS Optimizations on AMD Instinct MI450 GPUs
Learn how to optimize LDS traffic in Gluon kernels on AMD Instinct MI450 GPUs using transposed loads and partition-conflict-free layouts.
Memory Instruction Scheduling for Lock-Stepped Kernels on AMD Instinct™ MI300X: Introducing the Series
Explore how instruction scheduling eases stalls on AMD Instinct MI300X in a new blog series. This intro covers the motivating example and methodology.
Using ODC to Accelerate AMD SFT Training
Learn how we ported ODC on-demand P2P communication to AMD Instinct MI300X to cut FSDP bubbles and speed up variable-length SFT training.
AMD GPU Operator v1.5.0: DRA Support, Automated GPU Node Recovery, and Expanded Kubernetes Infrastructure Control
Discover how AMD GPU Operator v1.5.0 improves GPU scheduling, automates node recovery, and expands Kubernetes control.