Developers Blogs - Page 2#
MoE Training Optimization with Primus
Learn how to speed up MoE training on AMD Instinct GPUs with Primus: a fused MoE megakernel, FP8/MXFP8 expert GEMMs, and training-at-scale tuning.
hipCIM 26.06: GPU-Accelerated Whole-Slide Image I/O on AMD Instinct™ GPUs
In this blog you will see how hipCIM 26.06 reads whole-slide images on AMD Instinct™ GPUs, and how fast and faithfully it decodes them.
FP16 GEMM Optimization on AMD RDNA™ 3 and RDNA™ 4 Architectures
Learn how to build an FP16 GEMM kernel with WMMA on AMD RDNA 3 and RDNA 4, one optimization at a time, and approach hipBLASLt performance.
Completing the GPU Performance Picture: Understanding TAF Alongside Peak FLOPs and MAF
Learn how Typical Attained FLOPs complements Peak FLOPs and Max-Achievable FLOPs, including the methodology and MI325X results
ROCm 10.1: Breaking the Data-Movement Bottleneck
ROCm 10.1 targets the data-movement bottleneck with AMD Infinity Storage, NUMA-aware memory, and a modernized stack.
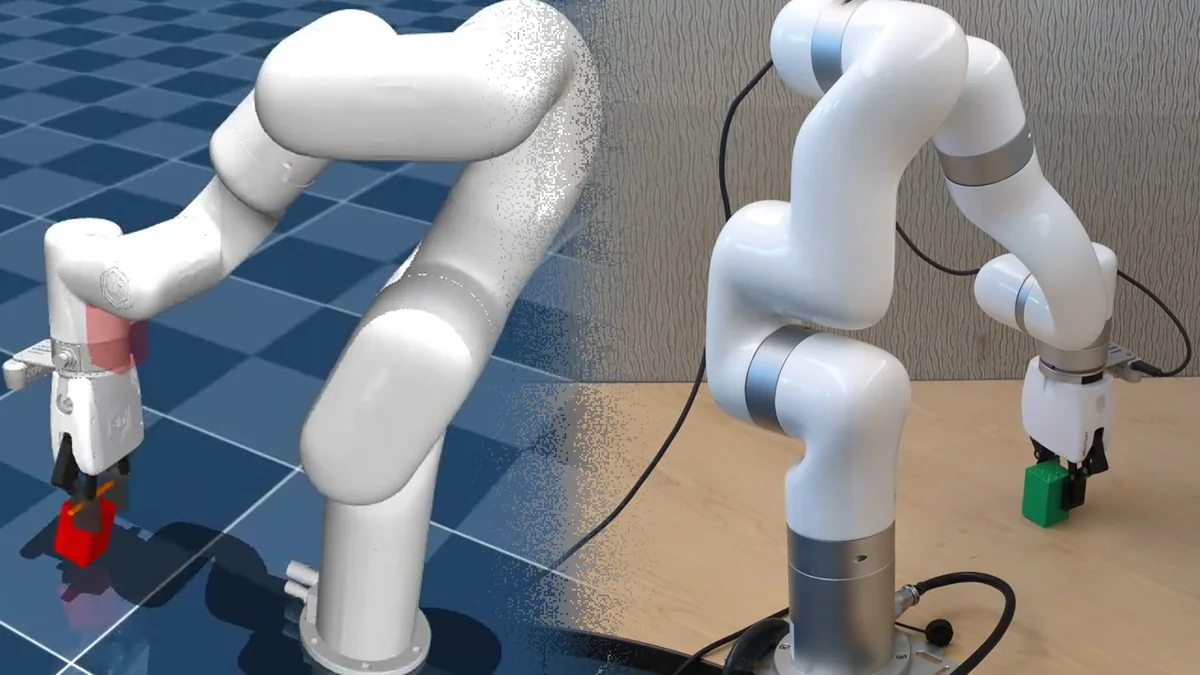
Unlocking Sim2Real for a Robotic Arm with RL Accelerated by AMD Instinct GPUs
Train an XArm-6 pick-and-lift policy with PPO in MuJoCo Warp on AMD Instinct GPUs, then transfer it to the real robot.
Debugging Logprob Mismatches in LLM Reinforcement Learning
Learn to debug logprob mismatches between rollout and training with Qwen3 examples on AMD Instinct MI355X GPUs.
Performance Profiling on AMD GPUs - Part 6: Advanced Thread Trace (ATT) - The Microscope for Your Application
Explore rocprofv3 ATT and ROCprof Compute Viewer to trace GPU kernels and explain stalls, waits, and memory-bound performance.
Hyperloom: A Multi-Agent Harness for Autonomous Inference Optimization on AMD GPUs
Hyperloom is a multi-agent harness that autonomously optimizes LLM inference on AMD Instinct GPUs, reaching a median 1.73x throughput gain.
Thread Trace Part 1: ROCprof Compute Viewer
Learn to capture thread traces with rocprofv3 and analyze instruction timing, stalls, utilization, and counters in ROCprof Compute Viewer.
Iteratively Tuning hipBLASLt TensileLite Kernels: A Smaller Search, a Faster Kernel
Learn why a small iterative search beats a big one-shot sweep for hipBLASLt TensileLite kernels, in less time and with no risk of regression.
Enabling DeepSeek-V4-Flash Training on AMD Instinct MI355X GPUs with Primus
DeepSeek-V4-Flash training on AMD Instinct GPUs with Primus: model architecture introduction, performance projection, kernel optimizations, and how to reproduce.