Developers Blogs#
GLM-5.2 AgentX on AMD Instinct MI355X: Boosting Throughput and Interactivity
Learn how cache and kernel optimizations raised GLM-5.2 AgentX throughput and interactivity on AMD Instinct MI355X.
FlyDSL Mono Kernels for High-Interactivity LLM Serving in ATOM
FlyDSL mono kernels cut decode latency in ATOM, with MiniMax-M3 and DeepSeek-V4.1 results.
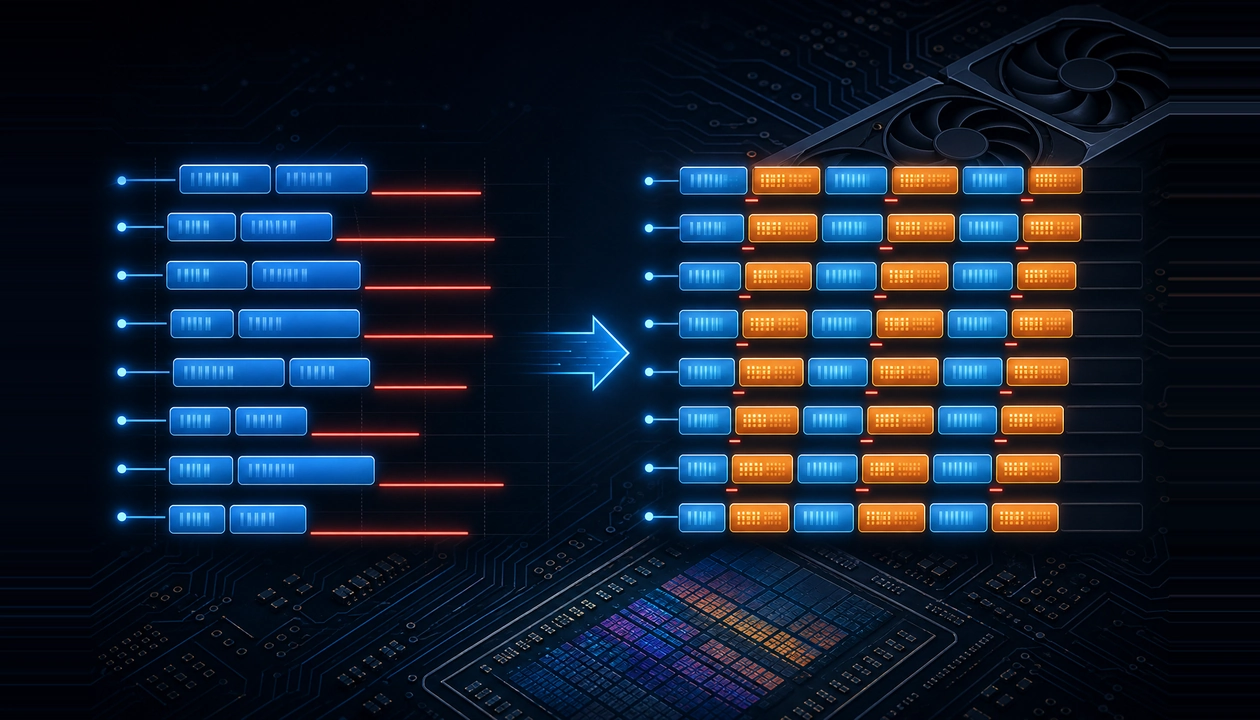
Device Memory Load Issue Stalls and Scheduling Opportunities in Lock-Stepped Kernels on AMD Instinct™ MI300X
Diagnosing and reducing device-memory load issue stalls in lock-stepped kernels on AMD Instinct MI300X by interleaving compute.
Faster Stable Diffusion on AMD Ryzen™ AI with TeaCache
In this blog, you will learn how to speed up Stable Diffusion 3 and 3.5 on AMD Ryzen AI NPUs with TeaCache, without retraining.
Bringing the MONAI Model Zoo to AMD Instinct™ GPUs: Validated Inference on ROCm
Learn how to run validated inference for five MONAI Model Zoo bundles on AMD Instinct™ GPUs using a ROCm overlay.
Two Waves, One Stage Apart: Warp-Pipelining Triton GEMMs on AMD Instinct
Use warp-pipelining to overlap matrix work and data preparation in compute-bound Triton GEMMs on AMD Instinct GPUs.
Training EAGLE3 Speculative Decoding Draft Models on AMD Instinct MI350X with AMD Quark
Learn how the AMD Quark team trains EAGLE3.1 draft models from scratch on AMD Instinct MI350X GPUs using ROCm, vLLM, TorchSpec, and SPEED-Bench.
Group-GEMM in XLA: Making Mixture-of-Experts Fast and Memory-Efficient
Learn how to make JAX/MaxText MoE training more efficient with two new OpenXLA Group-GEMM backends for ragged-dot: ROCm hipBLASLt and generic Triton.
Accelerating MONAI Digital-Pathology Pipelines on AMD Instinct™ GPUs with hipCIM
In this blog you will measure a MONAI digital-pathology pipeline on AMD Instinct™ GPUs using hipCIM as the WSIReader backend.
Ultralytics YOLO on AMD GPUs: Train, Run, and Deploy with ROCm™
Learn how to train, run, and deploy Ultralytics YOLO26 models on AMD GPUs with PyTorch on ROCm and MIGraphX, starting with Ultralytics 8.4.171.
FP8 GEMM Optimization on AMD RDNA™ 4 Architecture
Learn how to port an FP16 GEMM kernel to FP8 on AMD RDNA 4 and use the smaller element size to unlock larger tiles and deeper K slices.
Scaling 3D Gaussian Splatting with Distributed Compute: Why One GPU Is Never Enough
Learn how to scale 3D Gaussian splatting across GPUs with distributed training, RCCL, and real-world optimization tips for AMD Instinct GPUs