Applications & models#
Explore the latest blogs about applications and models in the ROCm ecosystem, including machine learning frameworks, AI models, and application case studies.
Nitro-P: Pixel-Space Text-to-Image via Hierarchical Semantic-to-Pixel Generation
Nitro-P is an E-MMDiT-based pixel-space text-to-image model. It uses lower FLOPs while delivering evaluation metrics and visual quality comparable to latent-space text-to-image models.
FlashInfer on ROCm 10.1: The FlashInfer API with Automatic Kernel Routing
Explore the new attention and fused ops in FlashInfer on ROCm: the upstream API, with each call routed to optimized AITER or in-tree HIP kernels.
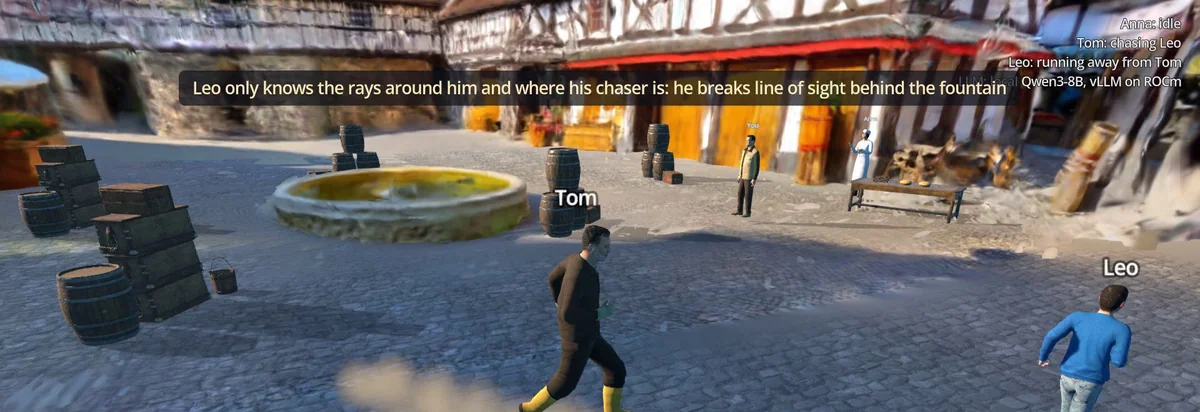
From a Text Prompt to a Playable 3D World: World Models, LLM NPCs, and RL on AMD Radeon™ Graphics
Turn a text prompt into a playable 3D world on one AMD Radeon graphics card with ROCm software: a video world model, Gaussian splats, LLM-driven NPCs and an RL agent.
Reproducing AMD MLPerf Training v6.1 Submission Result
Learn how to reproduce AMD's MLPerf Training v6.1 submission result.

Technical Deep Dive into AMD MLPerf Training v6.1 Results
In this blog, we share the technical details of how we accomplish the results in our MLPerf Training v6.1 submission.
Beyond Embedding Quantization: Quark UINT4 Qwen3.8-Flash-Next on Ryzen AI Halo
Explore n-gram table choices for Qwen3.8-Flash-Next with AMD Quark UINT4, including accuracy and response-length tradeoffs.
AMD Life Science 26.08: A Complete Medical Imaging Stack on AMD Instinct™ GPUs
Explore the AMD Life Science 26.08 medical-imaging stack on AMD Instinct™ GPUs, from image I/O through inference to annotation.
Accelerating GLM-5.2 on AMD Instinct MI355X: EvalScope Benchmarks with Prefix Caching
Learn how to optimize GLM-5.2 FP8 long-context inference on AMD Instinct MI355X GPUs using prefix caching and end-to-end inference stack tuning.
Parallelism for Long-Context Serving: GLM-5.3-Flash on MI300X
Measured throughput of GLM-5.3-Flash on MI300X: how KV-cache capacity shapes TP8 and DP8+EP8 serving, with BF16 and FP8 KV cache.
MONAILabel 0.8.5 on AMD Instinct™ GPUs: Interactive Medical-Image Annotation
Learn how to run MONAILabel 0.8.5 for interactive medical-image annotation on AMD Instinct™ GPUs.
Online Quantization: Smooth Path from One Checkpoint to Any Desired Serving Scenario
Learn how AMD Quark's online quantization quantizes LLM weights at load time across vLLM, ATOM, and SGLang, with per-layer mixed FP8/MXFP4 recipes.
Quark Mixed-Precision Quantization for Wan2.2 Video Generation on AMD Instinct GPUs
Apply AMD Quark mixed-precision MXFP4 quantization to Wan2.2-T2V-A14B video generation with calibration-driven block selection.