Recent Posts#
AMD Instinct MI455X vs MI355X: A Technical Look at the Advancing AI 2026 Inference Numbers
Explore the MI455X vs MI355X inference numbers from Advancing AI 2026, and learn how each benchmark was measured and what it really means.
DI Series: Serving Kimi-K3 MXFP4 Wide-EP Disaggregated on AMD Instinct MI300X and MI325X
Learn how to serve a 1.4 TiB Kimi-K3 MXFP4 mixture-of-experts model disaggregated across AMD Instinct MI300X and MI325X GPUs.
Pre-Training Hybrid LLMs from Scratch in Primus on AMD Instinct™ GPUs
Pre-train hybrid LLMs mixing MLA attention with Gated DeltaNet, Kimi Delta Attention and Mamba2 mixers on AMD Instinct MI355X GPUs, with open recipes.
Completing the GPU Performance Picture: Understanding TAF Alongside Peak FLOPs and MAF
Learn how Typical Attained FLOPs complements Peak FLOPs and Max-Achievable FLOPs, including the methodology and MI325X results
ROCm 10.1: Breaking the Data-Movement Bottleneck
ROCm 10.1 targets the data-movement bottleneck with AMD Infinity Storage, NUMA-aware memory, and a modernized stack.
Automating Performance Bottleneck Identification with the TraceLens Agent
TraceLens Agent is an agentic workflow that examines GPU traces to deliver a prioritized optimization report, detailing root causes and fixes.
Running MolmoAct2 Robot Policy on an AMD Ryzen AI Max+ 395 Mini PC
In this tutorial, users are introduced to a state of the art vision-language-action model and the steps to implement the model directly optimized for the AMD Ryzen AI Max+ 395 Computer.
AIM: Unified User Experience from Profile Discovery to Deployment
Learn how AIMs offer a unified user experience as you explore and deploy them across AMD Instinct, Radeon PRO, and EPYC.
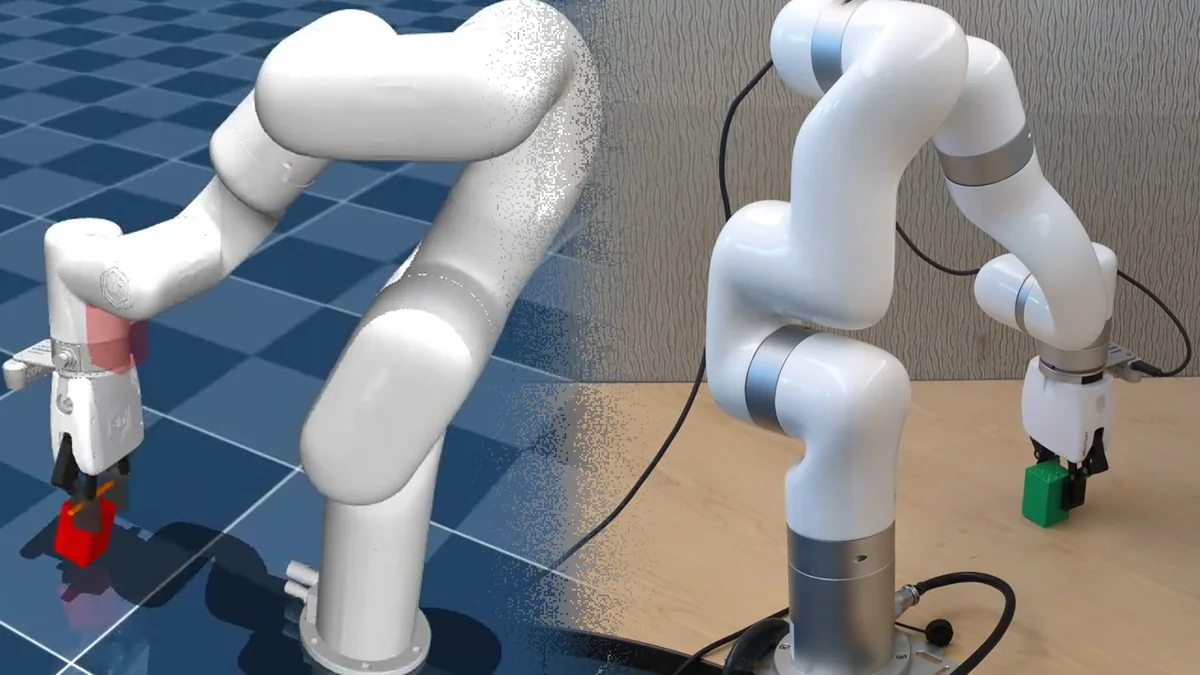
Unlocking Sim2Real for a Robotic Arm with RL Accelerated by AMD Instinct GPUs
Train an XArm-6 pick-and-lift policy with PPO in MuJoCo Warp on AMD Instinct GPUs, then transfer it to the real robot.
Verl 0.9.0 on ROCm™ 10.0: Next-Generation RL Post-Training on AMD Instinct™ GPUs
Enable Verl 0.9.0 on ROCm™ 10. Native AMD platform support, vLLM 0.27 and SGLang in one image, and updated async GRPO/DAPO recipes on AMD Instinct™ GPUs.
UltraQuant on AMD Instinct: More Efficient Agentic Serving for Qwen3.8-MXFP4
A native 4-bit MXFP4 KV cache that speeds up Qwen3.8 decode over 8-bit KV on AMD Instinct MI355X, with no accuracy loss.
Model Weight Profiles: Where Do the Parameters Go?
Introduce Model Weight Profiles and compare embeddings, attention, and dense layers so checkpoint size and quantization savings make sense.