AI - Applications & Models#
Micro-World 2: Streaming Real-time Interactive World Model
This blog demonstrates how Micro-World 2 combines precisely annotated action data, four-step diffusion distillation, and ROCm-optimized inference to deliver controllable, long-horizon, real-time world generation on a single AMD Instinct GPU through a fully open-source pipeline.
Optimizing World Action Models on AMD GPUs
Speed up World Action Models on AMD GPUs with GEAK kernels, fewer denoising steps, and latent actions, cutting FastWAM latency 25× at about 97 percent success.
Introducing rocOpt: GPU-Accelerated Decision Optimization on AMD ROCm
Run large-scale MILP, LP, QP, and vehicle routing problems on AMD Instinct GPUs - introducing rocopt, optimization built for ROCm.
Long Context, One Node: Serving GLM-5.3-FP8 on MI300X with DP8+EP8
Learn how to serve GLM-5.3-FP8 on one AMD Instinct™ MI300X node with DP8+EP8 and vLLM v0.28 for long-context workloads, and compare it with TP=8.
Pre-Training Hybrid LLMs from Scratch in Primus on AMD Instinct™ GPUs
Pre-train hybrid LLMs mixing MLA attention with Gated DeltaNet, Kimi Delta Attention and Mamba2 mixers on AMD Instinct MI355X GPUs, with open recipes.
Completing the GPU Performance Picture: Understanding TAF Alongside Peak FLOPs and MAF
Learn how Typical Attained FLOPs complements Peak FLOPs and Max-Achievable FLOPs, including the methodology and MI325X results
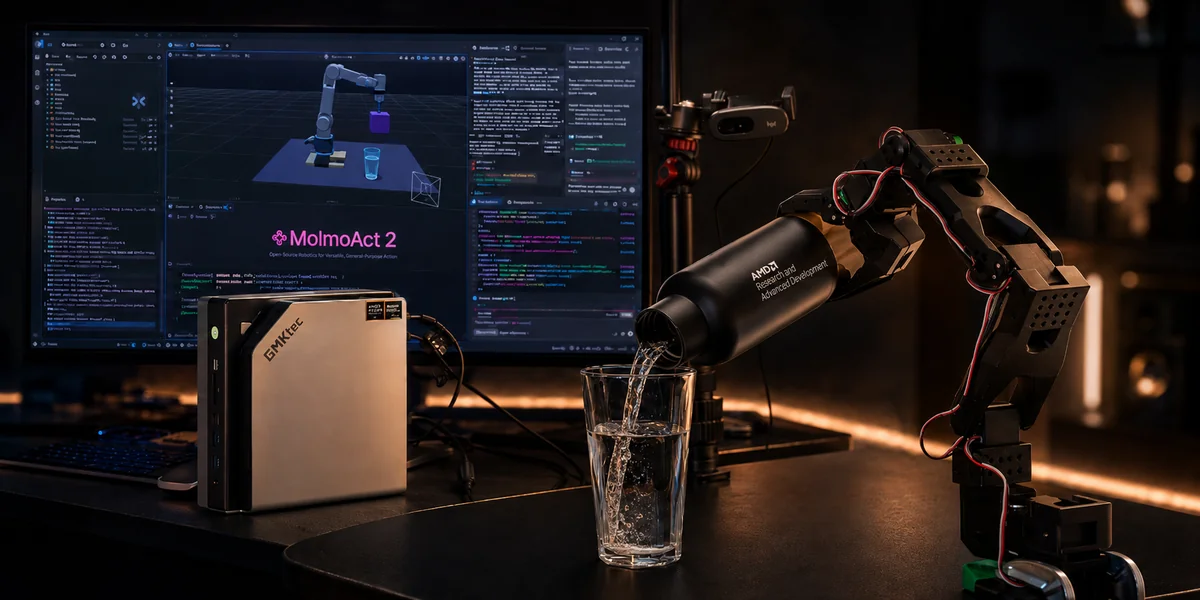
Running MolmoAct2 Robot Policy on an AMD Ryzen AI Max+ 395 Mini PC
In this tutorial, users are introduced to a state of the art vision-language-action model and the steps to implement the model directly optimized for the AMD Ryzen AI Max+ 395 Computer.
AIM: Unified User Experience from Profile Discovery to Deployment
Learn how AIMs offer a unified user experience as you explore and deploy them across AMD Instinct, Radeon PRO, and EPYC.
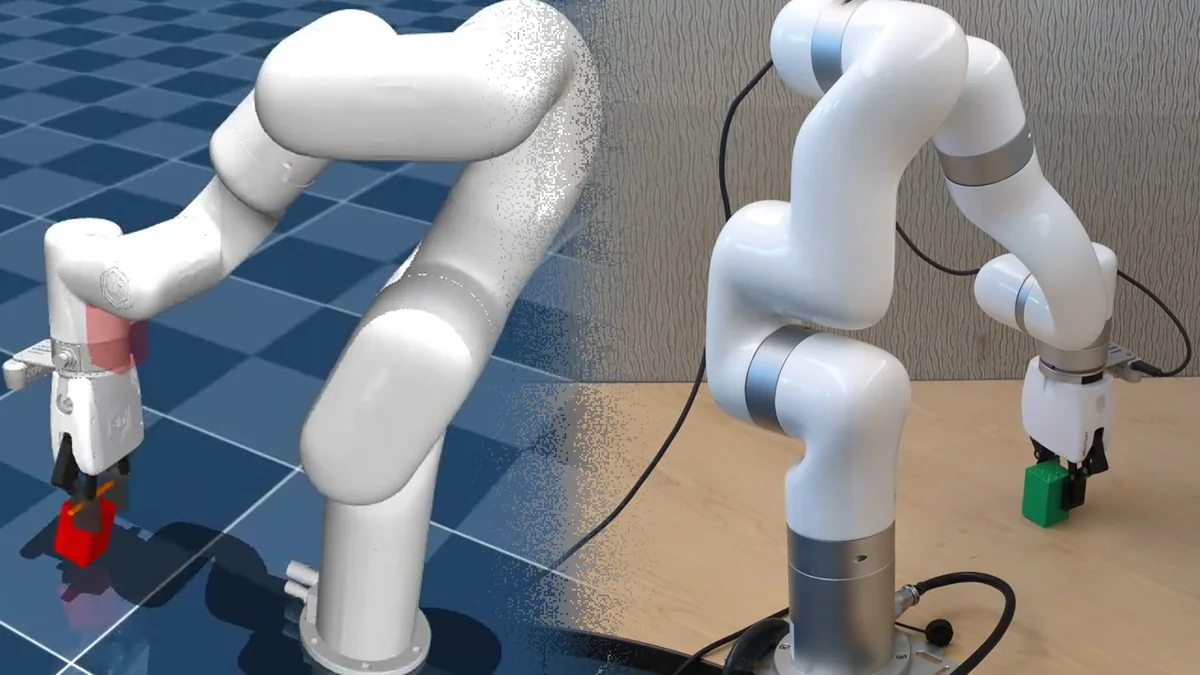
Unlocking Sim2Real for a Robotic Arm with RL Accelerated by AMD Instinct GPUs
Train an XArm-6 pick-and-lift policy with PPO in MuJoCo Warp on AMD Instinct GPUs, then transfer it to the real robot.
Verl 0.9.0 on ROCm™ 10.0: Next-Generation RL Post-Training on AMD Instinct™ GPUs
Enable Verl 0.9.0 on ROCm™ 10. Native AMD platform support, vLLM 0.27 and SGLang in one image, and updated async GRPO/DAPO recipes on AMD Instinct™ GPUs.
Model Weight Profiles: Where Do the Parameters Go?
Introduce Model Weight Profiles and compare embeddings, attention, and dense layers so checkpoint size and quantization savings make sense.
Local Quantization and Multi-Backend Deployment with AMD Quark on Strix Halo
Quantize a 35B MoE model directly on AMD Strix Halo with AMD Quark, export to GGUF and safetensors, validate with llama.cpp and vLLM, and deploy through Lemonade.