AI - Software Tools & Optimizations - Page 3#
Enabling DeepSeek-V4-Flash Training on AMD Instinct MI355X GPUs with Primus
DeepSeek-V4-Flash training on AMD Instinct GPUs with Primus: model architecture introduction, performance projection, kernel optimizations, and how to reproduce.
Optimizing ATOM and vLLM-ATOM for High-Interactivity Inference
Cut per-token latency on AMD Instinct MI355X GPUs: see how ATOM, vLLM-ATOM, and AITER strip fixed costs out of the LLM decode path.
4-bit KV Caching in LMCache: Offloading Quantized KV Beyond HBM for Context-Heavy Agents on AMD MI355X
Combining 4-bit KV quantization (TurboQuant) with KV offload (LMCache) on AMD MI355X nearly doubles serving goodput for long-context agents.
DI Series: Scaling GLM-5.1-FP8 to 64 MI300X GPUs
Scale GLM-5.1-FP8 long-context serving beyond a single node on AMD Instinct MI300X with WideEP prefill-decode disaggregation and MoRI.
Exploring XGBoost: A Deep Dive
A single source explanation of XGBoost features and its working principles.
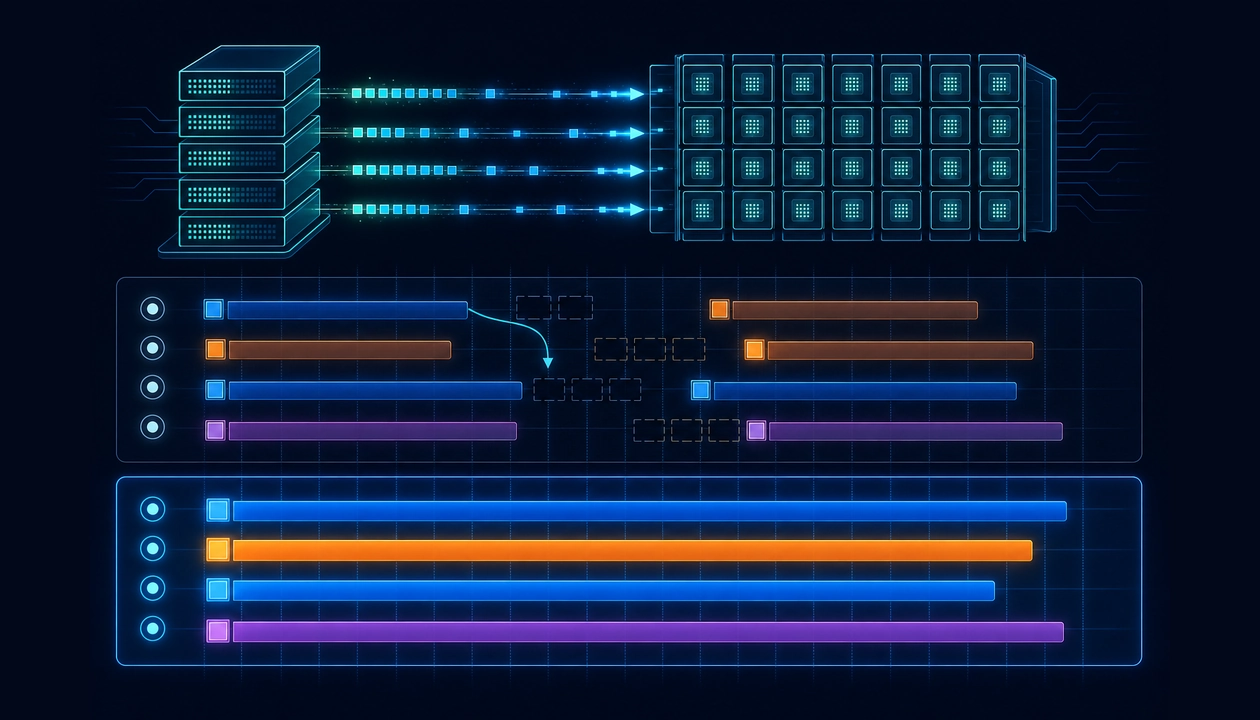
Memory Instruction Scheduling for Lock-Stepped Kernels on AMD Instinct™ MI300X: Introducing the Series
Explore how instruction scheduling eases stalls on AMD Instinct MI300X in a new blog series. This intro covers the motivating example and methodology.
Bring Claude Code On‑Prem with AMD Instinct GPUs
Start running Claude Code securely with a self-hosted SGLang LLM on AMD Instinct MI355X GPUs.
Production-Ready MXFP4 Online Rotation with Fused Kernels on AMD Instinct™ MI355X
Learn how fused Gluon (Triton) kernels cut MXFP4 online-rotation overhead to near-zero on AMD Instinct MI355X, making it production-ready.
Closing the GPU Cluster Validation Gap: A Kubernetes-Native Approach with CVF
Learn how to validate AMD GPU clusters end-to-end with CVF: hardware acceptance, mesh bandwidth, RDMA, and RCCL testing in one pipeline.
AMD GPU Operator v1.5.0: DRA Support, Automated GPU Node Recovery, and Expanded Kubernetes Infrastructure Control
Discover how AMD GPU Operator v1.5.0 improves GPU scheduling, automates node recovery, and expands Kubernetes control.
Serve Kimi-K2.5-MXFP4 on MI355X with ATOM
Serve Kimi-K2.5-MXFP4 on MI355X with ATOM and gfx950 block-scaled FP4 kernels for optimized LLM inference.
Hyperloom - Autonomous Agentic Inference Optimization for AMD GPUs
Hyperloom is a new open-source, agentic system aimed at automating the time-consuming task of optimizing end-to-end inference workloads.