AI - Software Tools & Optimizations#
Introducing the ROCm Handbooks
Discover the ROCm handbooks: book-style HTML and PDF guides that take you from your first HIP kernel to optimizing code for AMD GPUs.
PrimusClaw: An Open-Source Managed Agent Runtime for AMD Instinct GPU Clusters
PrimusClaw is an open-source managed agent runtime that hosts durable, sandboxed agent sessions on your own AMD Instinct GPU clusters.
ROCm InferaSim: Cut LLM Serving Trial Costs and Deploy the Best Configuration
Learn how ROCm InferaSim predicts LLM serving performance on AMD Instinct GPUs from a few short runs, so you can deploy the best configuration.
From Operator to Kernel: Profile DeepSeek-V4-Flash in Primus with madengine
Profile an eight-layer training proxy derived from the DeepSeek-V4-Flash Primus configuration on eight MI350X GPUs with madengine and TraceLens, then turn operator-to-kernel insights into faster runs.
GLM-5.2 AgentX on AMD Instinct MI355X: Boosting Throughput and Interactivity
Learn how cache and kernel optimizations raised GLM-5.2 AgentX throughput and interactivity on AMD Instinct MI355X.
FlyDSL Mono Kernels for High-Interactivity LLM Serving in ATOM
FlyDSL mono kernels cut decode latency in ATOM, with MiniMax-M3 and DeepSeek-V4.1 results.
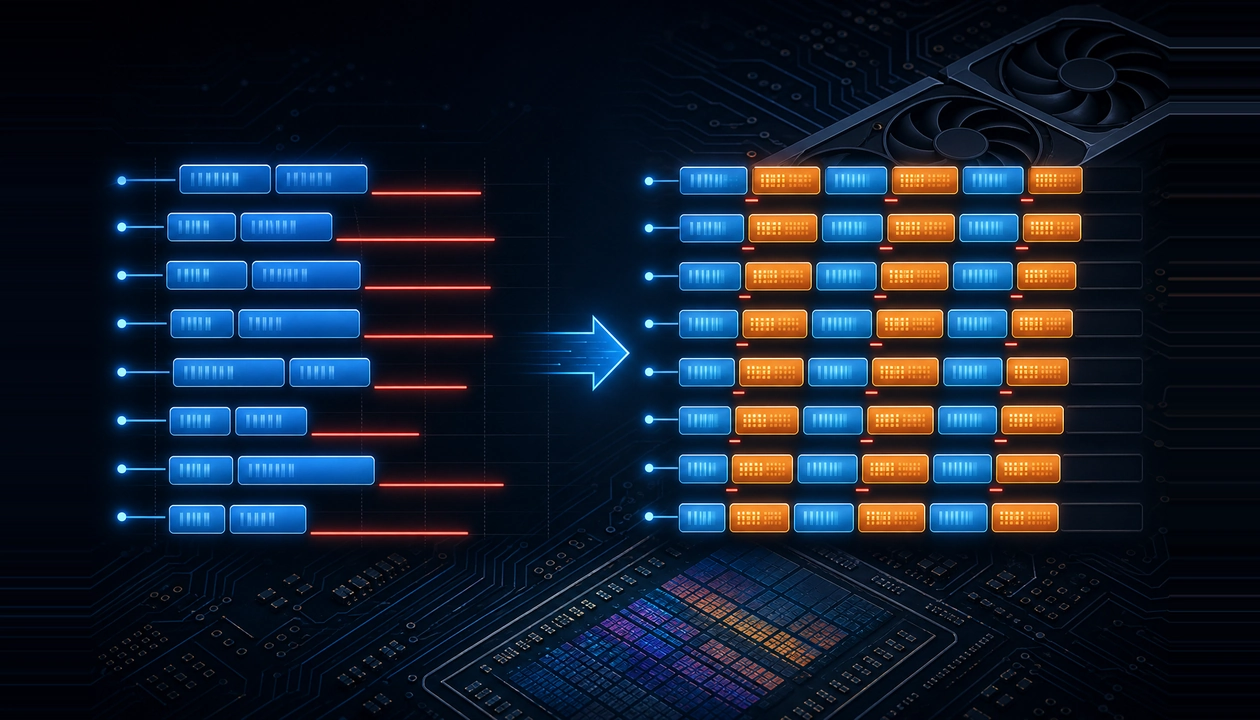
Device Memory Load Issue Stalls and Scheduling Opportunities in Lock-Stepped Kernels on AMD Instinct™ MI300X
Diagnosing and reducing device-memory load issue stalls in lock-stepped kernels on AMD Instinct MI300X by interleaving compute.
Faster Stable Diffusion on AMD Ryzen™ AI with TeaCache
In this blog, you will learn how to speed up Stable Diffusion 3 and 3.5 on AMD Ryzen AI NPUs with TeaCache, without retraining.
Two Waves, One Stage Apart: Warp-Pipelining Triton GEMMs on AMD Instinct
Use warp-pipelining to overlap matrix work and data preparation in compute-bound Triton GEMMs on AMD Instinct GPUs.
Group-GEMM in XLA: Making Mixture-of-Experts Fast and Memory-Efficient
Learn how to make JAX/MaxText MoE training more efficient with two new OpenXLA Group-GEMM backends for ragged-dot: ROCm hipBLASLt and generic Triton.
MoE Training Optimization with Primus
Learn how to speed up MoE training on AMD Instinct GPUs with Primus: a fused MoE megakernel, FP8/MXFP8 expert GEMMs, and training-at-scale tuning.
hipCIM 26.06: GPU-Accelerated Whole-Slide Image I/O on AMD Instinct™ GPUs
In this blog you will see how hipCIM 26.06 reads whole-slide images on AMD Instinct™ GPUs, and how fast and faithfully it decodes them.