Software tools & optimizations#
Discover the latest blogs about ROCm software tools, libraries, and performance optimizations to help you get the most out of your AMD hardware.
An AITER Pin Keyed by Kernel Text: Faster Glue Than the Inductor Default
Learn how an AITER pin keyed by kernel text beats Inductor's default glue config, and how it compares with open-list autotune.
Keep the Agent Warm: How ATOM Serves AgentX Workloads on AMD Instinct MI355X GPUs
Learn how ATOM keeps AgentX coding sessions warm on AMD Instinct™ MI355X GPUs, from prefix and state reuse to prefill scheduling and fused decode kernels, using Kimi-K3.
GPU-Initiated DMA Copy Engines in RCCL and rocSHMEM
Learn how GPU-initiated SDMA engines in RCCL and rocSHMEM offload data transfers to free compute units and maximize scale-up bandwidth.
Introducing the ROCm Handbooks
Discover the ROCm handbooks: book-style HTML and PDF guides that take you from your first HIP kernel to optimizing code for AMD GPUs.
PrimusClaw: An Open-Source Managed Agent Runtime for AMD Instinct GPU Clusters
PrimusClaw is an open-source managed agent runtime that hosts durable, sandboxed agent sessions on your own AMD Instinct GPU clusters.
ROCm InferaSim: Cut LLM Serving Trial Costs and Deploy the Best Configuration
Learn how ROCm InferaSim predicts LLM serving performance on AMD Instinct GPUs from a few short runs, so you can deploy the best configuration.
From Operator to Kernel: Profile DeepSeek-V4-Flash in Primus with madengine
Profile an eight-layer training proxy derived from the DeepSeek-V4-Flash Primus configuration on eight MI350X GPUs with madengine and TraceLens, then turn operator-to-kernel insights into faster runs.
Performance Profiling on AMD GPUs - Part 7: AI/PyTorch® Edition
Profile and optimize a PyTorch Evoformer (TinyOpenFold) training workload on AMD Instinct GPUs using rocprofv3, rocprof-compute, and rocprof-sys.
GLM-5.2 AgentX on AMD Instinct MI355X: Boosting Throughput and Interactivity
Learn how cache and kernel optimizations raised GLM-5.2 AgentX throughput and interactivity on AMD Instinct MI355X.
FlyDSL Mono Kernels for High-Interactivity LLM Serving in ATOM
FlyDSL mono kernels cut decode latency in ATOM, with MiniMax-M3 and DeepSeek-V4.1 results.
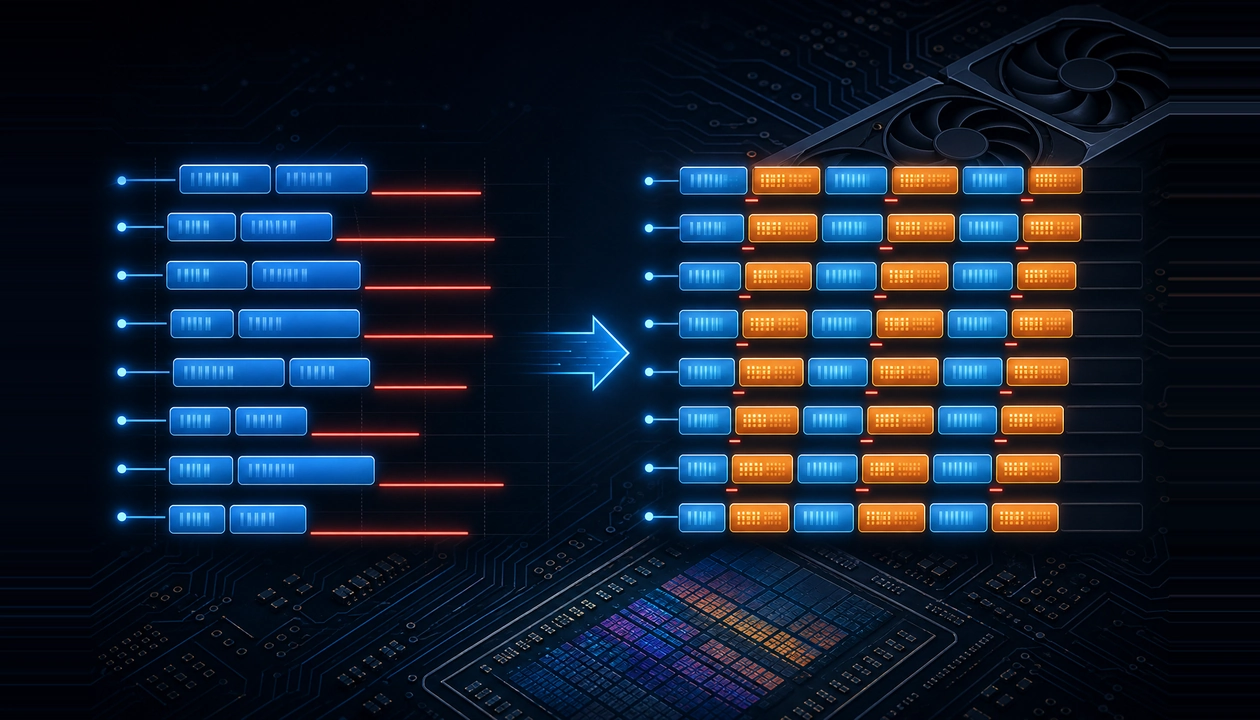
Device Memory Load Issue Stalls and Scheduling Opportunities in Lock-Stepped Kernels on AMD Instinct™ MI300X
Diagnosing and reducing device-memory load issue stalls in lock-stepped kernels on AMD Instinct MI300X by interleaving compute.
Faster Stable Diffusion on AMD Ryzen™ AI with TeaCache
In this blog, you will learn how to speed up Stable Diffusion 3 and 3.5 on AMD Ryzen AI NPUs with TeaCache, without retraining.